Latest News
* On February, 2023, WhoIsWho Toolkit is released! (https://github.com/allanchen95/WhoIsWho).
* On August, 2022, na-v3.1 version of data specified for the Incorrect Assignment Detection (IND) task has been launched! The corresponding contest is coming soon!
* On December, 2021, the official website, http://whoiswho.biendata.xyz/, with the regular leaderboard based on the latest version, na-v3 has been launched!
* On May, 2021, a new competition based on the latest version, na-v3, has been submitted to IJCAI 2021 on the website https://biendata.xyz/competition/who-is-who2021/. We honestly invite all the researchers of interest to attend our competition!
* On May, 2020, na-v2 version of data was released, and corresponding competition had been launched!
* On October, 2019, na-v1 version of data was released, and corresponding competition had been launched!
Overview
Name Disambiguation, aiming at disambiguating WhoIsWho, is a key and also a very tough problem in many online systems such as social search and academic search. Currently, the rapid growth of the literature around the world makes the problem more difficult and urgent in both academic and industrial areas. To resolve the disambiguation problem, a large-scale and high-quality benchmark is indispensable. Thereby, we aim at building the world's largest manually-labeled name disambiguation dataset and proposing corresponding disambiguation tasks to provide a general benchmark for evaluating relevant disambiguation methods.
Statistics. We already have released three versions of the dataset, which contains more than 1,000,000 papers. To our best knowledge, WhoIsWho owns the largest manually-labeled name disambiguation dataset in the world. The statistics are shown as below (#: the number of),
| Version | #Names | #Authors | #Papers | Date |
| V1 | 421 | 45,187 | 399,255 | 2019.10.1 |
| V2 | 231 | 13,662 | 228,683 | 2020.5.20 |
| V3 | 480 | 12,431 | 285,252 | 2021.3.31 |
| V3.1 | 1,327 | 1,381 | 273,773 | 2022.8.7 |
| Total | 2,459 | 72,609 | 1,102,249 | --- |
Previous Contests. We have held three name disambiguation competitions with two basic tasks (see Task Description.) based on na-v1, na-v2, and na-v3, and attracted more than 3,000 researchers to join in (see Previous Leardboard).
Regular Leaderboard. The latest version na-v3 serves as the regular benchmark with the same competition setting. That means you can leverage all the data from na-v1 and na-v2 to support your training process, and evaluate your powerful model on the test-set of na-v3. Your model performance will be listed on the regular leaderboard.
Incoming Contest. The contest based on the na-v3.1 dataset with the new task of Incorrect Assignment Detextion is coming soon!
WhoIsWho Toolkit. (https://github.com/allanchen95/WhoIsWho) By automating data loading, feature creation, model construction, and evaluation processes, the WhoIsWho toolkit is easy for researchers to use and let them develop new name disambiguation approaches.
We encourage more researchers to join us and generate more interesting ideas to promote relevant academic and industry areas! If you have any questions or suggestions, please send a mail to oagwhoiswho@gmail.com.
Task Description
Background. The past decades have witnessed a huge proliferation of research papers in all fields of science. For example, Google Scholar, Bing Academic Search, and AMiner have all indexed about 300 million papers. Thus, the author name ambiguity problem has become increasingly sophisticated in modern digital libraries. Through comprehensive studying, we define three basic tasks in the WhoIsWho series contests to benchmark disambiguation algorithms. These tasks shed light on the whole life cycle of the name disambiguation problems in online digital libraries.
Task 1: From-Scatch Name Disambiguation (SND)
Task Description. At the beginning of building digital libraries, we need to partition a large number of published papers into groups, each of which represents papers that belong to a single person. To achieve this, we formalize from-scratch name disambiguation as a clustering problem.
Task 2: Real-time Name Disambiguation (RND) (or Incremental Name Disambiguation)
The online academic systems have already constructed a large number of author profiles, so the most urgent problem is to assign newly-arrived papers to the existing author profiles efficiently.
Task Description. Given a set of unassigned papers and a group of existing author profiles, researchers need to assign unassigned papers to the right author profiles or return NIL (When there are no right author profiles). To this end, we formalize the real-time name disambiguation as a classification problem.
(Note: NIL conditions should be considered, which correspond to the scenarios that newly researchers published their first paper. On this scene, the online systems do not contain their profiles, so the disambiguation algorithm shouldn’t assign these papers to any existing author.)
Task 3: Incorrect Assignment Detection (IND)
Task Description. As inevitable cumulative errors brought via the methods of SND and RND greatly affect the efficacy of subsequent assignments, Incorrect Assignment Detection is a vital task to detect and remove wrongly-assigned papers.
Evaluation Metrics & Examples [Click]
Data Download
na-v3.1 (Incorrect Assignment Detection)
Train.
- train_author.json [Download]
- train_pub.json [Download]
Data Format Descriptions [Download]
Validation.
- ind_valid_author.json [Download] : Is organized in the same format as train_author.json
- ind_valid_pub.json [Download]
- ind_valid_example_submission_auc.json [Download]: Submission example for AUC
- ind_valid_example_submission_map.json [Download]: Submission example for MAP, the participator needs to rank all papers of each author according to the likelihood that the paper is an incorrect assignment in descending order.
Test.
- ind_test_author.json [Download]
- ind_test_pub.json [Download]
---------------------------------------------------------------------------------------------------------
na-v3 (Regular Benchmark.)
Competition Format.
The na-v3 competition data split.
Train.
- train_author.json [Download]
- train_pub.json [Download]
Data Format Descriptions [Download]
Validation.
I. From Scratch Name Disambiguation
- sna_valid_author_raw.json [Download]
- sna_valid_pub.json [Download]
- sna_valid_example_evaluation_scratch.json [Download]
Data Format Descriptions [Download]
II. Real-time Name Disambiguation
- Existing Author Profiles.
- whole_author_profile.json [Download]
- whole_author_profile_pub.json [Download]
- New (Unassigned) Papers.
- cna_valid_unass_competition.json [Download]
- cna_valid_pub.json [Download]
- cna_valid_example_evaluation_continuous.json [Download]
- cna_valid_author_ground_truth.json [Download]
Data Format Descriptions [Download]
Test:
I. From-Scratch Name Disambiguation
- sna_test_author_raw.json [Download]:same as sna_valid_author_raw.json;
- sna_test_pub.json [Download]:the file contains the specific paper information which belongs to sna_test_author_raw.json (The same format with train_pub.json).
II. Real-time Name Disambiguation
- cna_test_unass_competition.json [Download]: same as cna_valid_unass_competition.json
- cna_test_pub.json [Download]: the file contains the specific paper information which belongs to cna_test_unass_competition.json (The same format with train_pub.json).
----------------------------------------------------------------------------------------------------------------------------------------------------
na-v1
Summary.
The whole dataset of na-v1 version.
- na_v1_author.json [Download]
- na_v1_pub.json [Download]
Data Format Descriptions [Download]
Competition Format.
The na-v1 competition data split.
Train.
- train_author.json [Download]
- train_pub.json [Download]
Data Format Descriptions [Download]
Validation.
I. From-Scratch Name Disambiguation
- sna_valid_author_raw.json [Download]
- sna_valid_pub.json [Download]
- sna_valid_example_evaluation_scratch.json [Download]
- sna_valid_author_ground_truth.json [Download]
Data Format Descriptions [Download]
II. Real-time Name Disambiguation
- Existing Author Profiles.
- whole_author_profile.json [Download]
- whole_author_profile_pub.json [Download]
- New (Unassigned) Papers.
- cna_valid_unass_competition.json [Download]
- cna_valid_pub.json [Download]
- cna_valid_example_evaluation_continuous.json [Download]
- cna_valid_author_ground_truth.json [Download]
Data Format Descriptions [Download]
Test:
I. From-Scratch Name Disambiguation
- sna_test_author_raw.json [Download]:same as sna_valid_author_raw.json;
- sna_test_pub.json [Download]:the file contains the specific paper information which belongs to sna_test_author_raw.json (The same format with train_pub.json).
- sna_test_author_ground_truth.json [Download]:the right clustering results of the sna_test_author_raw.json.
II. Real-time Name Disambiguation
- cna_test_unass_competition.json [Download]: same as cna_valid_unass_competition.json
- cna_test_pub.json [Download]: the file contains the specific paper information which belongs to cna_test_unass_competition.json (The same format with train_pub.json).
- cna_test_author_ground_truth.json [Download]: the right assignment results of the cna_test_unass_competition.json.
----------------------------------------------------------------------------------------------------------------------------------------------------------------
na-v2
Summary.
The whole dataset of na-v2 version.
- na_v2_author.json [Download]
- na_v2_pub.json [Download]
Data Format Descriptions [Download]
Competition Format.
The na-v2 competition data split.
Train.
- train_author.json [Download]
- train_pub.json [Download]
Data Format Descriptions [Download]
Validation.
I. From-Scratch Name Disambiguation
- sna_valid_author_raw.json [Download]
- sna_valid_pub.json [Download]
- sna_valid_example_evaluation_scratch.json [Download]
- sna_valid_author_ground_truth.json [Download]
Data Format Descriptions [Download]
II. Real-time Name Disambiguation
- Existing Author Profiles.
- whole_author_profile.json [Download]
- whole_author_profile_pub.json [Download]
- New (Unassigned) Papers.
- cna_valid_unass_competition.json [Download]
- cna_valid_pub.json [Download]
- cna_valid_example_evaluation_continuous.json [Download]
- cna_valid_author_ground_truth.json [Download]
Data Format Descriptions [Download]
Test:
I. From-Scratch Name Disambiguation
- sna_test_author_raw.json [Download]:same as sna_valid_author_raw.json;
- sna_test_pub.json [Download]:the file contains the specific paper information which belongs to sna_test_author_raw.json (The same format with train_pub.json).
- sna_test_author_ground_truth.json [Download]:the right clustering results of the sna_test_author_raw.json.
II. Real-time Name Disambiguation
- cna_test_unass_competition.json [Download]: same as cna_valid_unass_competition.json
- cna_test_pub.json [Download]: the file contains the specific paper information which belongs to cna_test_unass_competition.json (The same format with train_pub.json).
- cna_test_author_ground_truth.json [Download]: the right assignment results of the cna_test_unass_competition.json.
Note:
1. We did not release the test ground truth for a fair comparison. We recommend you to evaluate your models on the validation set first, and then submit your model and the detailed running documents to the mail: oagwhoiswho@gmail.com. Please give us a few days to evaluate your model, and we will send you a reply after the evaluation (we are constructing a public evaluation platform, which will be launched soon);
2. If you want to launch your model performance on the leaderboard, please inform us explicitly, and then introduce your model name and the author's affiliations.
Human Annotation
Data collection. We choose the common person names with high ambiguity from AMiner database, which contains academic data from AMiner, MAG, and Pubmed.
Specifically, the names with high ambiguity mean that there have several authors with the same name. Then for the author, we collect all the papers that belonged to the author to construct a three-level dictionary organizing as name-author-paper regime.
Then for each paper, we collect its title, coauthors, affiliations, keywords, and abstract as the paper attributes for further human annotation. What’s more, there are many papers that have not assigned to any author profiles yet. So we also collect these papers whose authors have the same name as chosen above. these papers denoted as unassigned papers may be assigned to some author profiles during latter human-annotation.
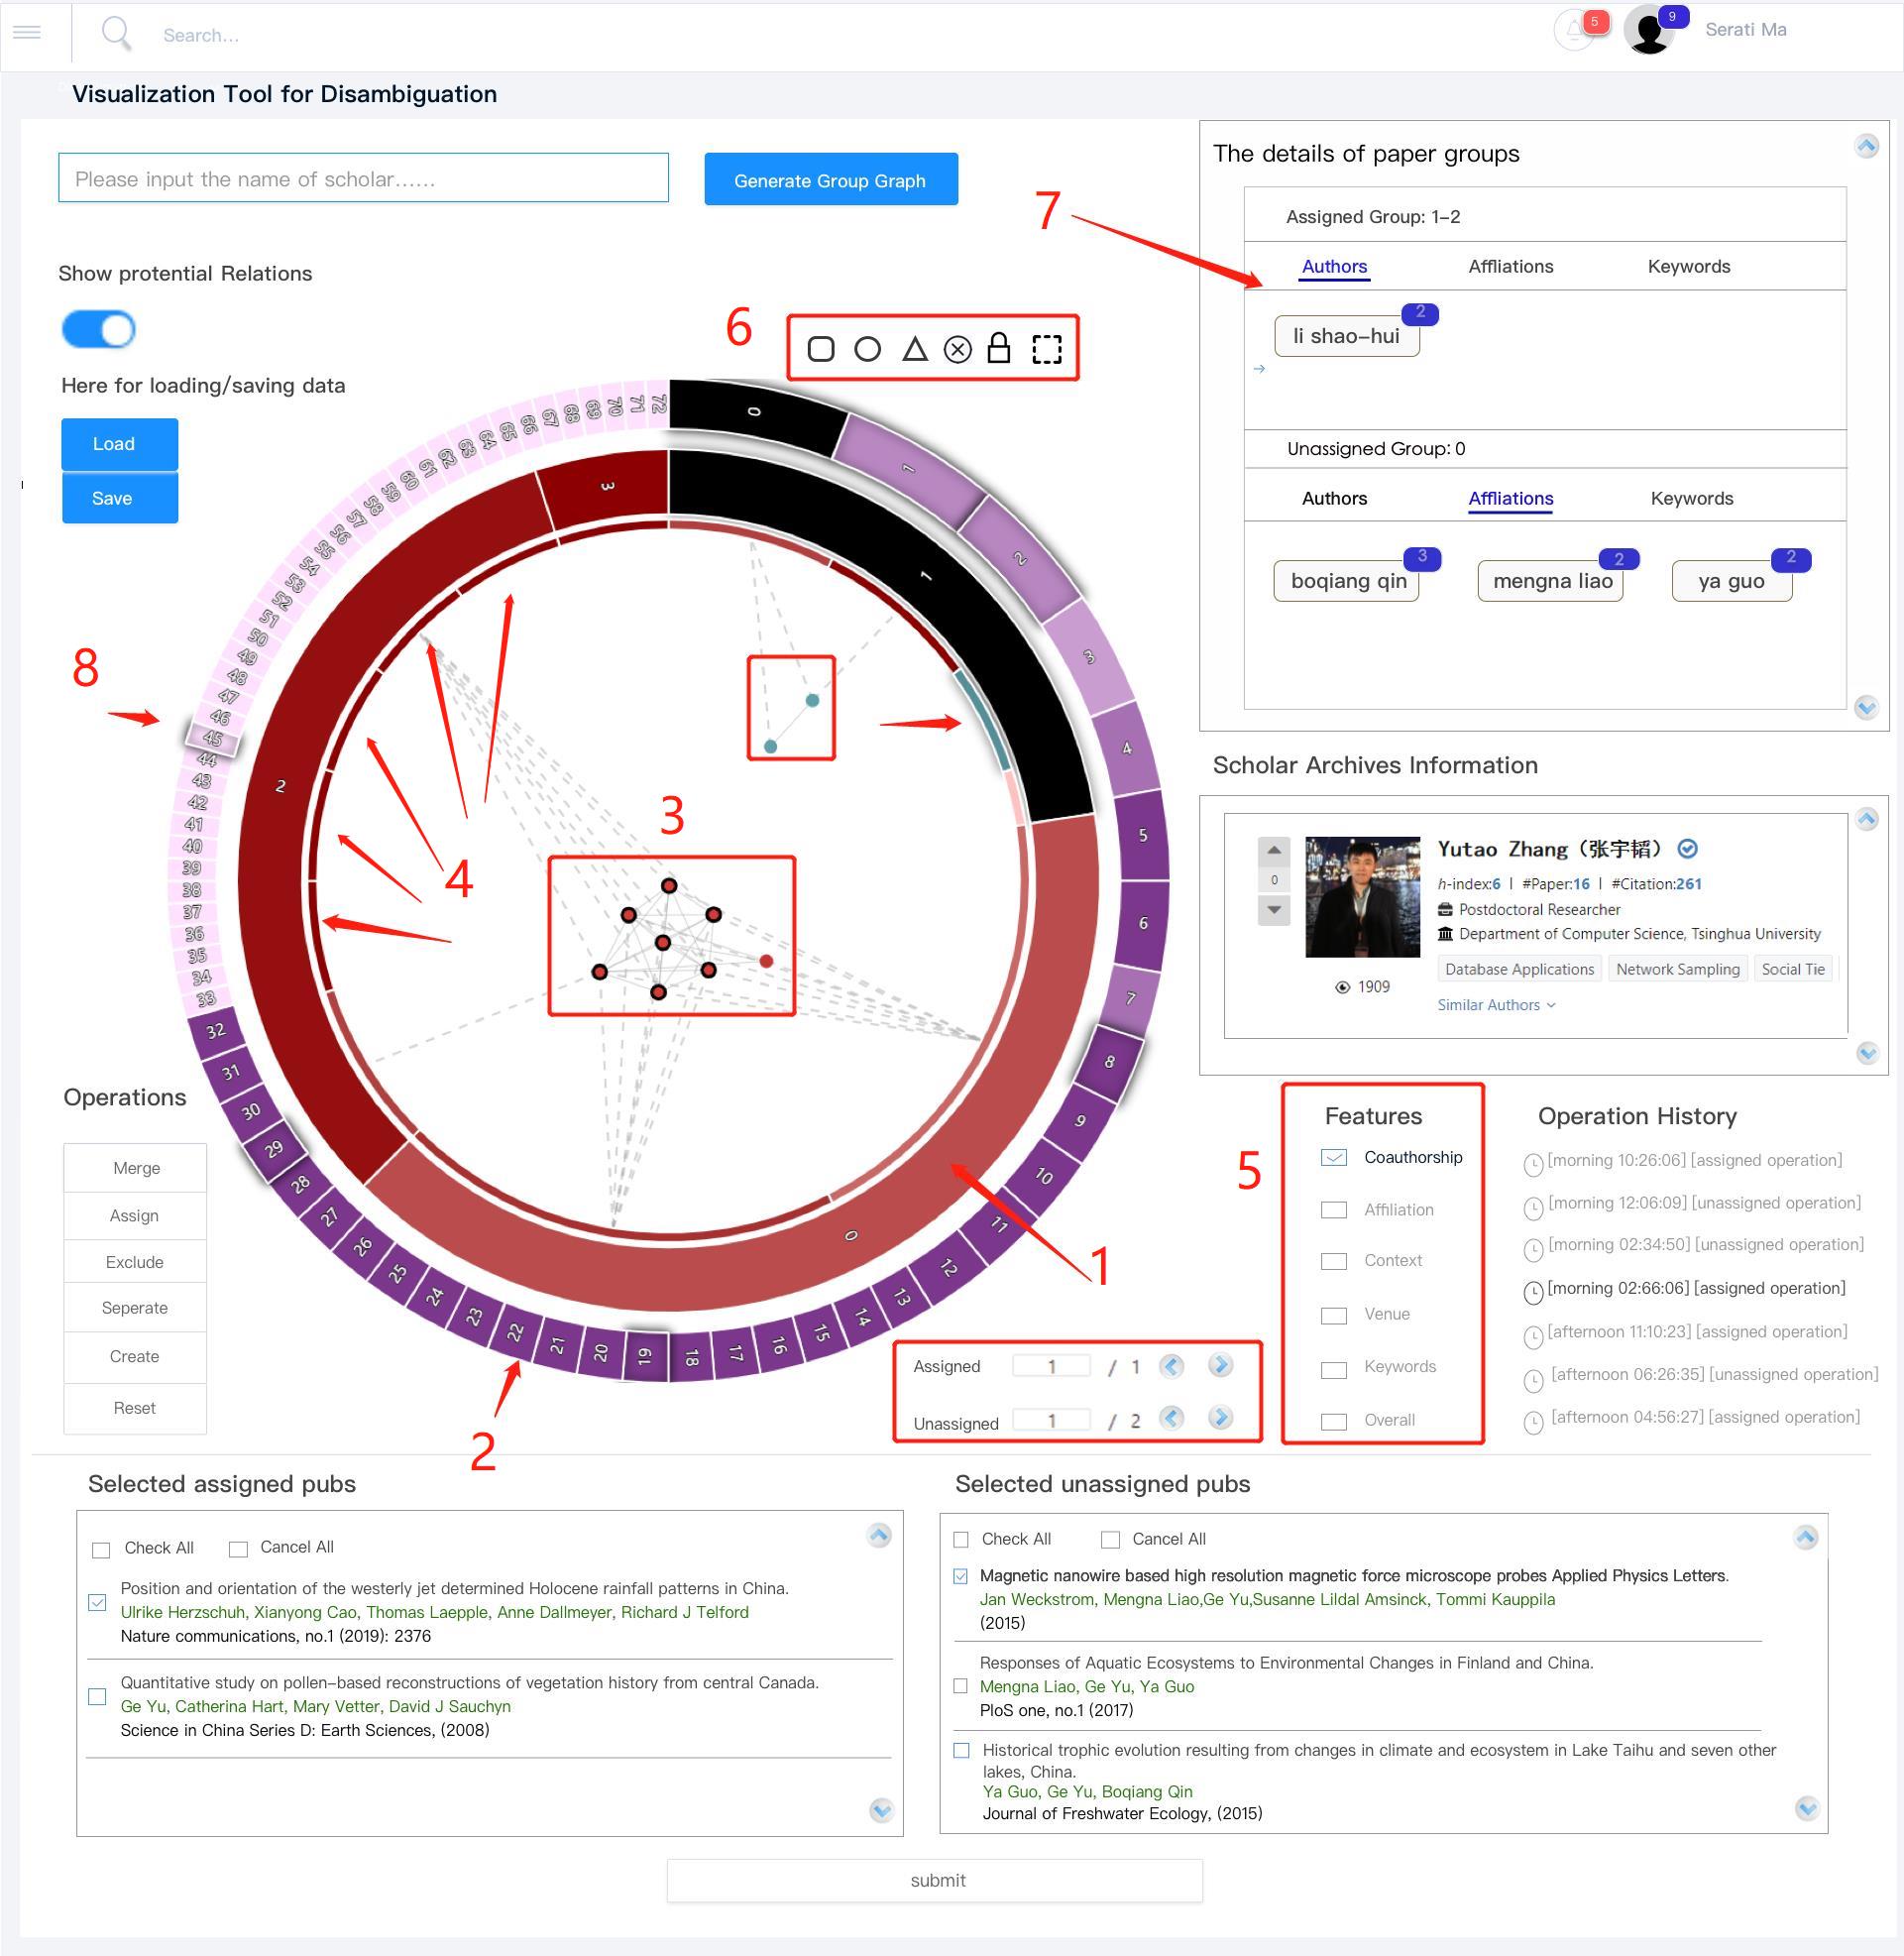
Human Annotation. The annotation process has four steps with AMiner Annotation Platform,
| Steps | #Annotators | Operations |
| Clean (Roughly) | 1 | 1. Delete the paper not belonging to the current author; 2. Split the original mixed author profiles, i.e., the profiles contain more than one author, into several new author profiles. |
| Validation | 3 | 1. Same as step “Clean” to further refine results. Majority voting is applied to solve the conflicts. |
| Add | 3 | 1. Assign the papers belonging to the unassigned papers as far as possible. Majority voting is applied to solve the conflicts. |
| Merge | 3 | 1. Merge several author profiles which is ought to be the same person to one author profile. Majority voting is applied to solve the conflicts. Then outputting the final human-annotated dataset. |
To summarize, each author profile has at least 4 annotators to check, which further confirms the high quality of the annotated dataset.
The shortcut of AMiner Annotation Platform is shown below, more details refer to THIS.
Previous Leaderboard
na-v1
I. From-Scratch Name Disambiguation
II. Real-time Name Disambiguation
na-v2
I. From-Scratch Name Disambiguation
II. Real-time Name Disambiguation
na-v3 (IJCAI'21 & Common Leaderboard)
Reference
If you think WhoIsWho is helpful to you, please cite the following papers,
[1]. Bo Chen, Jing Zhang, Jie Tang, Lingfan Cai, Zhaoyu Wang, Shu Zhao, Hong Chen, and Cuiping Li. CONNA: Addressing Name Disambiguation on The Fly. IEEE Transaction on Knowledge and Data Engineering (TKDE), 2020 (accepted). [PDF][data & code]
[2] Jie Tang, Jing Zhang, Limin Yao, Juanzi Li, Li Zhang, and Zhong Su. ArnetMiner: Extraction and Mining of Academic Social Networks. In Proceedings of the Fourteenth ACM SIGKDD International Conference on Knowledge Discovery and Data Mining (KDD'08), pages990-998. [PDF] [Slides] [System] [API] [Citation Data] [DBLP Citation Data] [Author-Conference-Topic (ACT) Model (source code)] [More Data] (Top 2 cited papers among all KDD 2008's papers, More...)
Sponsor