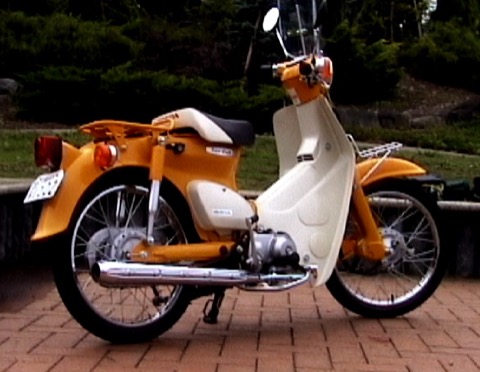
本田技研工业株式会社(Honda)成立于1948年,总部位于日本东京,注册资金为860亿日元,目前全球雇员总数达18万人以上。是世界上最大的摩托车生产厂家,汽车产量和规模也名列世界十大汽车厂家之列。 目前,本田技研工业株式会社已是一个跨国汽车、摩托车生产销售集团。它的产品除汽车摩托车外,还有发电机、农机等动力机械产品。

Automatic pain assessment from facial video remains challenging due to the spatial heterogeneity of pain-related facial cues. This study proposes ReFace, a spatial reorganization pipeline that divides facial input into four spatial quadrants before tokenization, rather than processing the entire face as a single region. Evaluated on the AI4Pain dataset, the proposed approach achieves 56.00% accuracy on the test set using video only, achieving the highest reported accuracy under the fixed AI4Pain benchmark protocol among the compared methods. Notably, the four-quadrant configuration processes the same total pixel budget as the full-face input, yet achieves higher accuracy, suggesting that spatial reorganization can improve performance under the proposed tokenization design. A single quadrant region, processing just one quarter of those pixels, remains competitive at a fraction of the computational cost.
Recent LLM agents benefit from skills for solving complex tasks. Skills encapsulate modular packages of procedural knowledge and instructions for performing specialized tasks, such as setting up a sandboxed environment, running a test suite, or refactoring a function across multiple files. As skill libraries grow and become reusable across tasks and domains, selecting an appropriate skill composition has emerged as a central bottleneck. Existing approaches fall into two categories. One exposes the agent's reasoning to the entire skill collection; the other performs skill retrieval via embeddings or LLM-based rerankers. Both provide useful insights; however, they miss the structural nature of skill composition, which is a joint decision over which skills, how many, and in what order – three dimensions that cannot be decoupled. We formalize this as structured skill composition: given a task and a skill library, predict an executable skill plan that jointly specifies the activated subset, count, and execution order. We propose SkillComposer, which instantiates structured skill composition as task-conditioned skill sequence prediction. SkillComposer uses a constrained autoregressive decoder over skill identifiers, so subset, count, and order emerge jointly from a single decoding pass, and dependencies between successive skills are captured naturally. We build a training set of task-composition pairs from a real, human-curated skill library. We then evaluate SkillComposer along two axes: composition quality on a held-out test set, and downstream task success on SkillsBench across two production-grade coding agents. On GPT-5.2-Codex, Gemini-3-Pro-Preview, SkillComposer raises the pass rate by +23.1, +18.2pp over the no-skill baseline, surpassing top-3 retrieval and matching the gold-skill retrieval upper bound at lower prompt-token cost.
Reach-Avoid-Stay (RAS) tasks are essential in applications where systems must safely reach a target set and remain within it under all bounded disturbances. Existing approaches either struggle to compute the maximal robust RAS set, the set of all states from which the RAS task is achievable, or are limited in handling general dynamic systems. To address these challenges, this paper proposes a two-step deep reinforcement learning framework that jointly learns the maximal robust RAS set and the corresponding control policy. The first step identifies the maximal robust control-invariant set within the target set and derives a policy that ensures the system remains within it. The second step computes the maximal robust reach-avoid (RA) set using this invariant set as the target, and it is proven that this RA set is equivalent to the maximal robust RAS set. Leveraging this result, a switching policy is constructed from the two step-wise policies, which constitutes a valid policy guaranteeing completion of the RAS task. Simulation results demonstrate that the proposed framework (1) computes the exact maximal robust RAS set in the absence of training errors, yielding the least restrictive RAS policy, and (2) identifies the RAS set with high accuracy while outperforming baseline methods on RAS tasks.
Stress is a dynamic process characterized by significant individual variability in facial expression. Traditional architectures, such as Recurrent Neural Networks (RNNs) and Convolutional Neural Networks (CNNs), often overlook person-specific baselines or lack the representational capacity to model the non-linear temporal progression of distress due to sequential bottlenecks and rigid grid-based constraints. Furthermore, many deep learning models lack the interpretability required for clinical deployment. This study introduces StressGAT, a Graph Attention Network that leverages the relational inductive bias of graph modeling to capture complex facial dynamics that indicate acute stress. By using Differential Action Units, the framework normalizes individual responses relative to neutral baselines to achieve personalized recognition. The proposed model achieves 88.62% accuracy on a diverse stress-induction cohort (58 participants) using a subject-independent, Leave-One-Subject-Out (LOSO) cross-validation protocol. Beyond predictive accuracy, the architecture integrates a Multiple Instance Learning (MIL) attention mechanism to identify peak stress intervals and reveal distinct expressivity phenotypes. By simultaneously optimizing for accuracy and interpretability, this framework provides a robust, explainable solution for personalized affective monitoring.
Where and when should a robot look during interaction with humans? Intuitively, human–human interaction serves as the blueprint. In such interactions, gaze plays a central role, both in visually guiding action and in signaling communication. Yet, most social robotics research still relies on the oversimplified eye–mind assumption, equating gaze with visual attention, and often implements gaze behaviors without accounting for perceptual limits or individual variability. We identify three core challenges at the intersection of psychology, visual perception, and robotics: (1) disentangling the dual functions of gaze, (2) understanding the visual perceptual mechanisms underlying gaze perception, and (3) adapting to individual, cultural, and clinical variability in gaze behavior. By examining these challenges in both robot interpretation and production of gaze, we argue that social robotics benefits from insights into human gaze and provides a powerful testbed for theory development, enabling controlled, interactive experiments that deepen our understanding of social attention. We conclude by conceptualizing social gaze as a soft-constraints inference and production process under uncertainty, linking visual perceptual mechanisms and social meaning.





