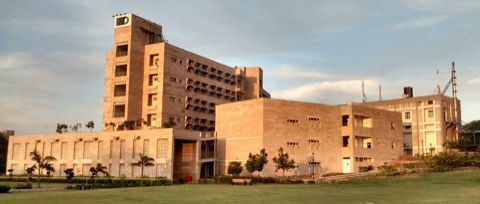
Indraprastha Institute of Information Technology, Delhi (Iṃdraprastha Sūcanā Praudyōgikī Saṃsthān Dillī, IIIT-Delhi or IIIT-D) is a state university located in Delhi, India. It is research-oriented with a focus on Computer Science and allied areas. The institute began with its first batch of 60 B.Tech students in 2008. As of 2019, the approved batch intake for B.Tech is 426 and for M.Tech is 203.

This study explores how Indian medical professionals navigate the complex ethical, cultural, and social terrain surrounding hymenoplasty, a surgical procedure rooted in patriarchal and societal norms linking a woman’s worth to virginity. Using a qualitative research design with in-depth interviews with gynecologists and cosmetic surgeons, this study reveals the deep internal and external conflicts that doctors face: balancing respect for patient autonomy with the recognition that requests for hymenoplasty are often driven by social coercion and the threat of stigmatization or harm. Key findings reveal that doctors’ communication styles and use of shared decision-making can either challenge or reinforce prevailing myths about virginity. The clinical space thus becomes a crucial site where gendered constructs are either contested or perpetuated. This study highlights an urgent need for institutional guidelines that prioritize ethical practice, mandatory counseling, and more robust informed consent processes for hymenoplasty. In the long term, comprehensive, age-appropriate sex education is recommended as a vital strategy to dismantle the persistent societal and cultural myths that fuel the demand for such procedures and to promote women’s autonomy and well-being.
Multimodal generative AI systems like Stable Diffusion, DALL-E, and MidJourney have fundamentally changed how synthetic images are created. These tools drive innovation but also enable the spread of misleading content, false information, and manipulated media. As generated images become harder to distinguish from photographs, detecting them has become an urgent priority. To combat this challenge, we release MS COCOAI, a novel dataset for AI generated image detection consisting of 96000 real and synthetic datapoints, built using the MS COCO dataset. To generate synthetic images, we use five generators: Stable Diffusion 3, Stable Diffusion 2.1, SDXL, DALL-E 3, and MidJourney v6. Based on the dataset, we propose two tasks: (1) classifying images as real or generated, and (2) identifying which model produced a given synthetic image. The dataset is available at https://huggingface.co/datasets/Rajarshi-Roy-research/Defactify_Image_Dataset.
Natural language processing (NLP) technologies are rapidly reshaping how language is created, processed, and analyzed by humans. With current and potential applications in hiring, law, healthcare, and other areas that impact people's lives, understanding and mitigating harms towards marginalized groups is critical. In this survey, we examine NLP research papers that explicitly address the relationship between LGBTQIA+ communities and NLP technologies. We systematically review all such papers published in the ACL Anthology, to answer the following research questions: (1) What are current research trends? (2) What gaps exist in terms of topics and methods? (3) What areas are open for future work? We find that while the number of papers on queer NLP has grown within the last few years, most papers take a reactive rather than a proactive approach, pointing out bias more often than mitigating it, and focusing on shortcomings of existing systems rather than creating new solutions. Our survey uncovers many opportunities for future work, especially regarding stakeholder involvement, intersectionality, interdisciplinarity, and languages other than English. We also offer an outlook from a queer studies perspective, highlighting understudied topics and gaps in the harms addressed in NLP papers. Beyond being a roadmap of what has been done, this survey is a call to action for work towards more just and inclusive NLP technologies.
Let R be a finite commutative chain ring, and let N be a positive integer with gcd(N,|R|) = 1. An additive cyclic code of length N over R is defined as an additive subgroup of RN, which is invariant under the cyclic shift operator on RN. In this paper, we first provide canonical form decompositions of additive cyclic codes of length N over R and their character-theoretic dual codes into linear codes over mixed alphabets of Galois rings, which are called their constituents. With the help of these decompositions, we further characterize all self-orthogonal, self-dual and complementary-dual additive cyclic codes of length N over R in terms of their constituents. When |R| is odd, we derive necessary and sufficient conditions for the existence of a self-dual additive cyclic code of length N over R. We also provide a method to construct and enumerate all self-orthogonal and self-dual additive cyclic codes of length N over R and obtain enumeration formulae for these two classes of codes under the assumption that |R| is odd. Besides this, we study and enumerate all complementary-dual additive cyclic codes of length N over R. We also illustrate these results with some examples.
We introduce HyperCap, the first large-scale hyperspectral captioning dataset designed to enhance model performance and effectiveness in remote sensing applications. Unlike traditional hyperspectral imaging (HSI) benchmarks, HyperCap integrates spectral data with pixel-wise textual annotations, enabling deeper semantic understanding. This dataset enhances model performance in tasks like classification and feature extraction, providing a valuable resource for advanced remote sensing applications. HyperCap is constructed from four benchmark datasets and annotated through a hybrid approach combining automated and manual methods to ensure accuracy and consistency. Empirical evaluations using state-of-the-art encoders and diverse fusion techniques demonstrate significant improvements in classification performance. These results underscore the potential of vision-language learning in HSI and position HyperCap as a foundational dataset for future research in the field. The code and dataset are available at https://github.com/arya-domain/HyperCap.





