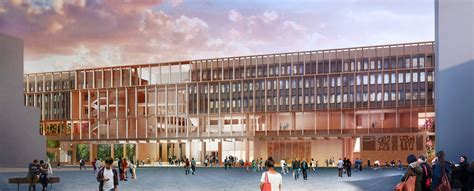
Télécom Paris (also known as ENST or Télécom or École nationale supérieure des télécommunications, also Télécom ParisTech until 2019) is a French public institution for higher education (grande école) and engineering research. Located in Palaiseau, it is also a member of the Institut Polytechnique de Paris and the Institut Mines-Télécom. In 2020 it was the fifth highest ranked French university in the World University Rankings, and the 188th highest ranked worldwide.In 1991, Télécom Paris and the EPFL collaborated and established a school named EURECOM located in Sophia-Antipolis. Students can now be admitted in two different curriculums, located either in the Paris or the Sophia-Antipolis campus.

Accurate trajectory prediction of vulnerable road users is a cornerstone of safe autonomous driving and intelligent transportation systems. While large-scale pre-training has advanced this field, achieving robust zero-shot generalization remains a critical challenge for real-world deployment, particularly when vehicles encounter unseen environments and heterogeneous sensor configurations (e.g., varying frame rates and observation horizons). In this work, we revisit zero-shot trajectory prediction from the perspective of distribution shifts and distinguish three transfer settings: temporal transfer, scene transfer, and joint scene–temporal transfer. Through systematic experiments, we show that temporal mismatch is a key source of failure in current pre-trained models. By isolating temporal configuration from dataset shift, we demonstrate that explicitly conditioning on temporal metadata provides a simple and highly effective solution. Building on this insight, we propose OmniTraj, a Transformer-based framework pre-trained on large-scale heterogeneous data with explicit temporal-aware design. OmniTraj is designed to handle omni-generalization in trajectory prediction, namely adaptability across temporal configuration and scene shifts. It achieves state-of-the-art zero-shot generalization under joint scene–temporal transfer, reducing prediction error by over 70%. Furthermore, it exhibits exceptional robustness in safety-critical edge cases with severely limited observations and maintains high few-shot data efficiency, paving the way for scalable, dataset-agnostic deployment in real-world autonomous systems. The code is publicly available: https://github.com/vita-epfl/omnitraj.
Cloud computing data centers handle highly variable workloads: job resource requirements can range from just one or few cores to thousands, and job service times can range from milliseconds to hours or days. This variability significantly limits the maximum achievable utilization of infrastructures. Queuing theory has addressed the study of these systems with the definition of the Multiserver-Job Queuing Model (MJQM), where s identical servers are present and job n requires alpha(n) of the s servers for a random amount of time sigma(n). The alpha(n) servers are occupied and released simultaneously. Unfortunately, despite its simple formulation, the MJQM remains elusive. For example, the MJQM stability condition has been derived only in particular cases. As a consequence, even applying Discrete-Event Simulation (DES) under high load becomes challenging, because stability cannot be determined a priori. In this paper, we analyze the MJQM with general independent arrival processes and service times under FCFS scheduling, using stochastic recurrence equations (SREs) and ergodic theory. Starting from the definition of the MJQM SRE, we prove the monotonicity and separability properties that allow us to apply an extension of Loynes' theorem, known as the monotone-separable framework, and formally define the MJQM stability condition. From these results, we introduce and implement two algorithms: the first one is used to draw sub-perfect samples (SPS) of the system's workload and the second one estimates the system's stability condition given the statistics of the jobs' input stream. The nature of the SPS algorithm allows for a massive GPU parallelization, thus greatly improving the efficiency in the estimation of performance metrics. The algorithm for the estimation of the stability condition solves an important problem for the analysis of MJQMs. We also define new metrics that capture the synchronization loss in MJQM systems and we show how these metrics can be efficiently evaluated using the SRE approach. Finally, we show that the approach proposed in this paper can be extended to more complicated systems, including MJQMs where resources have types.
Evaluating tabular generators remains a challenging problem, as the unique causal structural prior of heterogeneous tabular data does not lend itself to intuitive human inspection. Recent work has introduced structural fidelity as a tabular-specific evaluation dimension to assess whether synthetic data complies with the causal structures of real data. However, existing benchmarks often neglect the interplay between structural fidelity and conventional evaluation dimensions, thus failing to provide a holistic understanding of model performance. Moreover, they are typically limited to toy datasets, as quantifying existing structural fidelity metrics requires access to ground-truth causal structures, which are rarely available for real-world datasets. In this paper, we propose a novel evaluation framework that jointly considers structural fidelity and conventional evaluation dimensions. We introduce a new evaluation metric, global utility, which enables the assessment of structural fidelity even in the absence of ground-truth causal structures. In addition, we present TabStruct, a comprehensive evaluation benchmark offering large-scale quantitative analysis on 13 tabular generators from nine distinct categories, across 29 datasets. Our results demonstrate that global utility provides a task-independent, domain-agnostic lens for tabular generator performance. We release the TabStruct benchmark suite, including all datasets, evaluation pipelines, and raw results. Code is available at https://github.com/SilenceX12138/TabStruct.
Modern video generative models produce visually impressive results, yet frequently violate basic physical principles. We propose Proprio, a training-free framework that enables a frozen video generator to assess and improve the physical plausibility of its own outputs. Inspired by proprioception, the biological sense of one's own movement, Proprio treats the model's flow residual under controlled latent perturbations as a self-scoring signal. Samples that are better explained by the generator's learned dynamics induce smaller and more stable residuals. We aggregate this signal across timesteps and perturbations, focus it on motion-relevant regions with a dynamic spatiotemporal mask, and use it for best-of-N search, gradient-based self-refinement, or both. Across text-to-video and image-to-video benchmarks, Proprio consistently improves physical plausibility, outperforming VLM-based scoring, and external world-model baselines in several settings. With TurboWan2.2, Proprio improves Physics-IQ from 32.2 to 37.5 (+16.5
Prompting large language models (LLMs) to evaluate generated text, known as LLM-as-a-judge, has become a standard evaluation approach in natural language generation (NLG), but is primarily used as a quantitative tool, i.e. with numerical scores as main outputs. In this work, we propose LLM-as-a-qualitative-judge, an LLM-based evaluation approach with the main output being a structured report of common issue types in the NLG system outputs. Our approach is targeted at providing developers with meaningful insights on what improvements can be done to a given NLG system and consists of two main steps, namely open-ended per-instance issue analysis and clustering of the discovered issues using an intuitive cumulative algorithm. We also introduce a strategy for evaluating the proposed approach, coupled with 300 annotations of issues in instances from 12 NLG datasets. Our results show that LLM-as-a-qualitative-judge correctly recognizes instance-specific issues in 2/3 cases and is capable of producing error type reports resembling the reports composed by human annotators. Our code and data are publicly available at https://github.com/tunde-ajayi/llm-as-a-qualitative-judge.





