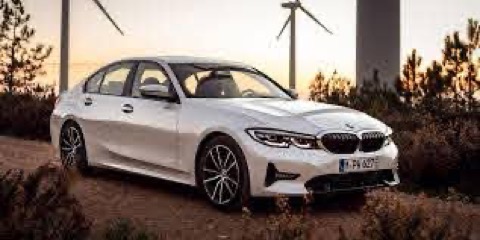
宝马公司是巴伐利亚机械制造厂股份公司的简称,1916年成立于德国慕尼黑,与菲亚特、福特、雷诺、劳斯莱斯相比显得年轻。但是在20世纪30年代它却制造出了世界上最好的跑车和豪华轿车,它从二战的破坏和50年代的财政衰退中恢复过来。 70年代早期,它再度成为世界高性能和豪华轿车市场上的主角之一,并一直延续至今。宝马的全称是巴伐利亚汽车制造厂。它是由一个制造飞机引擎的公司于1916年3月注册而成立的。这家公司第一个成功的产品是由费兹设计的直列六缸发动机,在第一次世界大战时装配在德国飞机上。德国王牌飞行员恩斯特·乌德特把他们成功的很大一部分归功于宝马的引擎。2018年10月,宝马集团和华晨汽车集团联合宣布,股东双方将延长华晨宝马的合资协议至2040年。

The combination of a node-based shape parameterization with parametric design is presented. The Vertex Morphing method is blended with rigid body parameters, including additional non-Euclidean geometric transformations. A rigid body representation is chosen, suitable for gradient-based shape optimization, which uses existing nodal sensitivity information. Inspired by the discretization-independent approach for the Vertex Morphing method based on the shape morphing functions, the effect of different design variable scaling strategies on gradient-based optimization with the selected rigid body parameterization is studied. In order to control the smoothness in the transition between design subdomains, that is, the regions that are controlled by the different design variables, we introduce blending functions. The variable scaling strategy is extended for the mixed parameterization to stabilize the influences of the design variables. Convergence speedups by mitigating the ill-conditioning with the help of the variable scaling approach are demonstrated in academic geometrical examples, and optimization improvements by selecting better local minima are presented in a structural problem. Furthermore, an industrial CFD application case supports the work.
Optimization via decoded quantum interferometry (DQI) has recently gained a great deal of attention as a promising avenue for solving optimization problems using quantum computers. In this paper, we apply DQI to an industrial optimization problem in the automotive industry: the vehicle option-package pricing problem. Our main contributions are (1) formulating the industrial problem as an integer linear program (ILP), (2) converting the ILP into instances of max-XORSAT, and (3) developing a detailed quantum circuit implementation for belief propagation, a heuristic algorithm for decoding low density parity-check codes. Thus, we provide a full implementation of the DQI algorithm using Belief Propagation, which can be applied to any industrially relevant ILP by first transforming it into a max-XORSAT instance. We also evaluate the effectiveness of our implementation by benchmarking it against both Gurobi and a random sampling baseline.
Electrolyte-motion–induced salt inhomogeneity (EMSI) is increasingly recognized as a failure mode in fast-charging. However, its generality beyond large jelly-roll cells has remained unclear. In this work, we present this effect for the first time in single-layer pouch cells. EMSI arises whenever two conditions coincide: charge-induced pore-volume reduction with pore filling ratio >1 and strong through-plane salt polarization. We reproduce the reported EMSI fingerprint, a reversible, week-scale rise in ohmic resistance accompanied by rate-dependent capacity loss and use it as a diagnostic marker. Direct mapping by ion chromatography and ATR-FTIR spectroscopy reveals centimeter-scale LiPF₆ gradients, with up to ∼3× center-to-edge differences across 2.5 cm after ∼20 equivalent fast-charge cycles. These gradients require nearly a week to dissipate and coincides with edge-localized Li deposition. Their homogenization is tracked by a reversible drop in high-frequency resistance during the cell rest period. A coupled pseudo-3D electrochemical-fluid model reproduces the experimental trends and illustrates how the resistance evolves. Parameter scans of electrolyte amount, charge/discharge rate, temperature, and silicon content chart the onset conditions and motivate actionable mitigation strategies. Together, these results establish EMSI as a general design and testing challenge across cell formats whenever electrode stacks are mechanically constrained.
Large Language Model (LLM)-based applications are increasingly deployed across various domains, including customer service, education, and mobility. However, these systems are prone to inaccurate, fictitious, or harmful responses, and their vast, high-dimensional input space makes systematic testing particularly challenging. To address this, we present STELLAR, an automated search-based testing framework for LLM-based applications that systematically uncovers text inputs leading to inappropriate system responses. Our framework models test generation as an optimization problem and discretizes the input space into stylistic, content-related, and perturbation features. Unlike prior work that focuses on prompt optimization or coverage heuristics, our work employs evolutionary optimization to dynamically explore feature combinations that are more likely to expose failures. We evaluate STELLAR on three LLM-based conversational question-answering systems. The first focuses on safety, benchmarking both public and proprietary LLMs against malicious or unsafe prompts. The second and third target navigation, using an open-source and an industrial retrieval-augmented system for in-vehicle venue recommendations. Overall, STELLAR exposes up to 4.3 times (average 2.5 times) more failures than the existing baseline approaches.
In-Car Conversational Question Answering (ConvQA) systems significantly enhance user experience by enabling seamless voice interactions. However, assessing their accuracy and reliability remains a challenge. This paper explores the use of Large Language Models (LLMs) alongside advanced prompting techniques and agent-based methods to evaluate the extent to which ConvQA system responses adhere to user utterances. The focus lies on contextual understanding, the ability to provide accurate venue recommendations considering the user constraints and situational context. To evaluate the utterance/response coherence using an LLM, we synthetically generate user utterances accompanied by correct but also modified failure-containing system responses. We use input-output, chain of thought, self-consistency prompting, as well as multi-agent prompting techniques, with 13 reasoning and non-reasoning LLMs, varying in model size and providers, from OpenAI, DeepSeek, Mistral AI, and Meta. We evaluate our approach on a case study that involves a user asking for restaurant recommendations. The most substantial improvements are observed for small non-reasoning models when applying advanced prompting techniques, in particular, when applying multi-agent prompting. However, non-reasoning models are significantly surpassed by reasoning models, where the best result is achieved with single-agent prompting incorporating self-consistency. Notably, the DeepSeek-R1 model achieves the highest F1-score of 0.99 at a cost of 0.002 USD per request. Overall, the best tradeoff between effectiveness and cost/time efficiency is achieved with the non-reasoning model DeepSeek-V3. Our results demonstrate that LLM-based evaluations offer a scalable and accurate alternative to traditional human-based evaluations for benchmarking contextual understanding in ConvQA systems.





